Server Log Analysis: Detect AI Crawlers and Optimize Access
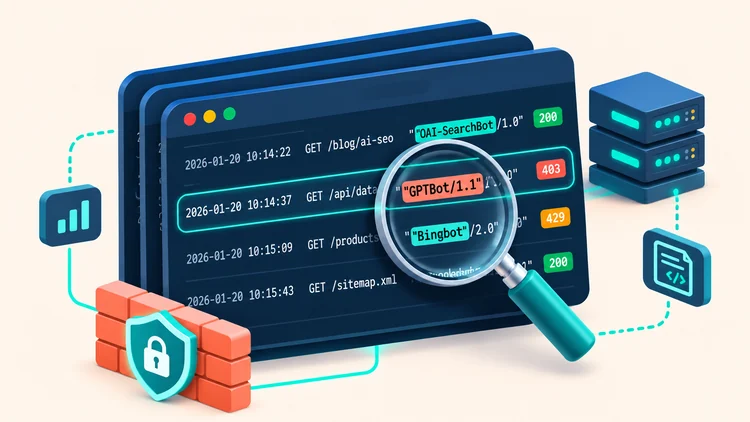
Server log analysis helps SEO and infrastructure teams determine which crawlers request website pages, whether those requests are successful, and where access fails. For AI search visibility, the useful question is not simply “Did a bot visit?” but “Was a verified crawler able to fetch the intended public content without security or technical errors?” This guide covers collection, identification, Cloudflare WAF investigation, remediation, and post-change validation.
Why analyze AI crawler logs?
Server logs provide request-level evidence that conventional SEO dashboards cannot show: source IP, User-Agent, requested path, timestamp, HTTP status, response duration, and the layer that handled the request. A request in the logs does not prove that a page was indexed, used to train a model, or cited in an AI answer. Conversely, a missing request in origin logs does not prove that no crawler accessed the website: a CDN may have served or blocked it upstream.
- Identify which important URL groups receive crawler requests and which are rarely accessed.
- Investigate spikes in
403,429, and5xxresponses. - Distinguish an origin-server error from a CDN/WAF action.
- Document crawler access changes after robots.txt, firewall, caching, or website releases.
Understand crawler types before changing access rules
| Crawler or agent | Typical purpose | Important distinction |
|---|---|---|
| OAI-SearchBot | OpenAI search discovery and access | Different from GPTBot; follow the provider's current documentation for controls and IP ranges. |
| GPTBot | OpenAI model-related crawling | Training-oriented crawling policies should not be confused with search discovery policies. |
| ChatGPT-User | User-initiated retrieval | May represent a specific user action rather than routine site-wide indexing. |
| Googlebot | Google Search crawling | Verify the Google source IP/PTR; User-Agent alone is spoofable. |
| Bingbot | Bing Search crawling | Verify its origin using Microsoft's official instructions. |
Operational rule: maintain a provider-specific inventory of the bots you intend to allow, limit, or block. Do not treat all automated visitors as AI search crawlers. A User-Agent string is a clue, not identity proof.
1. Collect complete access evidence
Gather origin access and error logs, reverse-proxy logs, and Cloudflare Security Events (or the equivalent CDN/WAF request logs). Where available, include Ray IDs, WAF action, matched rule ID, origin status, edge status, client IP, URL path, and request time. Edge and origin data should be compared before diagnosing a missing request.
| Field | Why it matters |
|---|---|
| Timestamp and time zone | Join records from different systems; normalize to UTC. |
| Client IP and trusted proxy headers | Verify origin without trusting an arbitrary forwarded header. |
| User-Agent and request path | Locate candidate crawler traffic and affected content. |
| HTTP status, bytes, response time | Find errors, incomplete responses, and latency changes. |
| CDN action, rule ID, Ray ID | Distinguish WAF challenges and blocks from origin failures. |
Use only trusted reverse-proxy configuration to obtain the actual client address; on Cloudflare-proxied sites, a raw origin connection IP may belong to Cloudflare. Define a retention policy appropriate to security needs, privacy requirements, and storage costs rather than assuming one mandatory retention period.
2. Inspect Linux web server logs
On a VPS running OpenLiteSpeed, Nginx, or Apache, first identify the actual log path for the vhost and web server version. The commands below are read-only examples; replace paths after verification. Avoid running a broad command against unknown locations as root.
# Find likely log configuration and files (paths vary)
sudo find /usr/local/lsws/logs /var/log/nginx /var/log/apache2 -maxdepth 2 -type f 2>/dev/null | head -50

# Candidate AI crawler requests from an access log
sudo grep -Ei 'OAI-SearchBot|GPTBot|ChatGPT-User|Bingbot|Googlebot' /path/to/access.log | tail -50

# Count candidate crawler requests by status (Combined Log format)
sudo grep -Ei 'OAI-SearchBot|GPTBot|ChatGPT-User' /path/to/access.log | awk '{print $9}' | sort | uniq -c | sort -nr

# Review rejected requests without modifying data
sudo grep -E '" (403|429|500|502|503|504) ' /path/to/access.log | tail -50
Check the format first: the awk '{print $9}' example assumes a conventional Combined Log layout. In JSON logs or customized OpenLiteSpeed formats, parse named fields with the appropriate tool instead of assuming a fixed column. When sharing sample logs, remove tokens, cookies, and personal data.
3. Verify that a crawler is genuine
- Read the claimed User-Agent and record the request source IP from trusted logs.
- For Googlebot, perform reverse DNS and forward verification, or compare against Google's published crawler IP ranges.
- For OpenAI bots, compare source IP against the currently published provider IP lists and use its crawler documentation. Do not assume a Google-style PTR hostname is available for every vendor.
- If using Cloudflare, review verified-bot classification and relevant WAF event metadata, subject to your plan's available features.
- Document the result as verified, unverified, or spoofed/suspicious; avoid broad allowances for unverified requests.
Official references: OpenAI web crawlers, Google crawler verification, and Cloudflare verified bots.
4. Diagnose 403, 429, and server errors
| Signal | Possible explanation | First check |
|---|---|---|
403 Forbidden |
WAF block, access policy, application rule, or origin permission | Match CDN request ID/time with origin logs and rule events. |
429 Too Many Requests |
Rate limiter or abusive traffic protection | Confirm source identity, request volume, limit scope, and retry behavior. |
5xx |
Application, upstream, timeout, or infrastructure error | Inspect origin error logs and edge/origin status separately. |
200 OK |
Successful HTTP response, not necessarily useful content | Check whether body contains correct public HTML instead of a challenge/empty shell. |
For a Cloudflare-managed property, check whether security settings such as AI bot blocking, managed robots.txt rules, custom WAF rules, and bot protection have intentionally limited access. Website owners may deliberately block some AI crawler classes while allowing search-focused crawlers. Do not interpret every block as an SEO defect.
5. Restore intended access without weakening security
- Confirm the business policy: which crawler type and which public URL paths are allowed?
- Verify the crawler identity using provider documentation or a trusted bot classification.
- Find the exact failing WAF/rate-limit rule and scope of affected paths.
- Apply the smallest practical exception by verified source and required path; avoid whitelisting a User-Agent alone.
- Preserve authentication, sensitive-path protections, abuse controls, and logging.
- Re-test from an approved environment, then watch genuine crawler logs for subsequent requests.
An HTTP 429 response with an appropriate Retry-After can communicate a rate limit, but it is not a guarantee that every AI crawler will retry in a predictable way. Likewise, a local curl request with a spoofed bot User-Agent verifies your server behavior for that request, not that the real vendor bot is authorized or will crawl successfully.
6. Review robots.txt, indexing directives, and rendered content
- Confirm the intended public URLs are crawlable under applicable robots.txt directives; review both origin and CDN-managed directives.
- Check that
noindex,X-Robots-Tag, incorrect canonicals, or login requirements are not unintentionally hiding public content. - Ensure important content can be retrieved as meaningful HTML without dependence on user interaction or authenticated APIs.
- Review redirect chains, incorrect 404/soft-404 responses, server timeouts, and language-specific URLs.
- Keep AI crawling, Google indexing, and citations as separate outcomes: successful fetches do not guarantee rankings or AI mentions.
7. Build an actionable monitoring dashboard
Segment data by verified provider, crawler role, affected website section, HTTP status, and time window. Track requests and unique URLs crawled, error share, P95 response time, top blocked paths, and changes after deployments. Add alerting for sustained increases in errors, but only after establishing a stable baseline and a minimum sample size to reduce false positives.
For AEO/GEO analysis, pair crawl-access evidence with independent query snapshots and traffic analytics. A request from a crawler does not reveal whether the information later appears in any particular AI answer.
8. Post-change verification: first 72 hours
- Immediately: save WAF configuration and verify the narrowly scoped rule change; run authorized HTTP checks.
- 0–24 hours: compare CDN decisions, origin statuses, error frequency, and page-body quality for affected URL samples.
- 24–72 hours: observe genuine, verified crawler requests if they occur; check whether repeated 403/429/5xx responses persist.
- Closeout: record affected URLs, verified identity, before/after metrics, the exact change, approver, and rollback method.
Not seeing a verified crawler again within 72 hours does not by itself mean the fix failed; individual crawler schedules are outside the site's control.
9. Incident report template
| Field | Example entry |
|---|---|
| Incident | Verified search crawler blocked on public article URLs |
| Time window | UTC start/end, with local time conversion for reporting |
| Evidence | CDN request IDs, WAF rule ID, sanitized request samples, origin status |
| Root cause | Specific custom rule or rate-limit condition |
| Remediation | Scoped exception approved by site/security owner |
| Validation | Test outcomes, subsequent verified traffic, remaining issues |
| Rollback | Saved rule configuration and restoration procedure |
Frequently asked questions
Does an OAI-SearchBot entry prove my page is cited in ChatGPT?
No. It records a request claiming that User-Agent. After verifying the source, it may provide evidence of access, but does not prove indexing, inclusion in an answer, or a citation.
Can I allow a crawler using only its User-Agent?
That is unsafe because headers can be spoofed. Use verified source information or trusted bot-classification controls and make narrowly scoped WAF exceptions.
Does a 200 response mean the content is accessible to AI?
Not necessarily. Confirm that the response includes the expected content and that other directives, authentication, or rendering behavior do not prevent access.
Should every AI crawler be allowed?
No. Crawling preferences should follow your business, legal, content-licensing, and security policies. Search crawling, training crawling, and user-initiated retrieval are different use cases.
Conclusion
Effective AI crawler analysis starts with trustworthy logs and accurate identity verification, then traces blocked requests across CDN, WAF, and origin infrastructure. Make the smallest approved configuration changes, retain security protections, and use independent evidence to evaluate search and AI visibility. The objective is controlled, reliable access to public content—not unrestricted bot access or guaranteed AI citations.
Questions & Comments
You can ask a question about this article. Viet SEO will review and reply after moderation.